
GPT-6.1 Terra API
GPT-6.1 Terra is OpenAI's balanced mid-tier model in the GPT-6.1 series, combining visual reasoning with fast, accurate computer operation.
GPT-6.1 Terra is a mid-tier model in OpenAI's three-tier GPT-6.1 series, positioned between the flagship GPT-6.1 Sol and the fast, low-cost GPT-6.1 Luna. It combines detailed visual reasoning with accurate computer operation and writes clearer, more natural prose. Announced and made available on October 26, 2026, through ChatGPT Work, Codex, and the API, it is designed as a fast and efficient option for everyday professional work.
The model supports text and image input with text output. It handles scoped code fixes, supports computer-use tasks with clearly defined outcomes, and is suited to agentic codebase investigation and iterative solution development. Everyday applications include drafting proposals, interpreting technical drawings, filling in forms, video editing, matching product photos with catalogs, and understanding complex documents.
At 16.1 seconds per task, it is reported as the fastest OpenAI model and the third fastest overall. Its error rate on error-inducing prompts at low reasoning effort is 16.7%, down from 53.6% for GPT-5.6 Terra. At max effort, the error rate is 4.3%. In the lineup, it sits below the flagship GPT-6.1 Sol and the top-tier GPT-6 Astra.
Updated:
MODEL ID
gpt-6.1-terra- Context
- 1.05M
- Max output
- 128K
- Recommended API
- responses
- Input
- file / image / text
- Output
- text
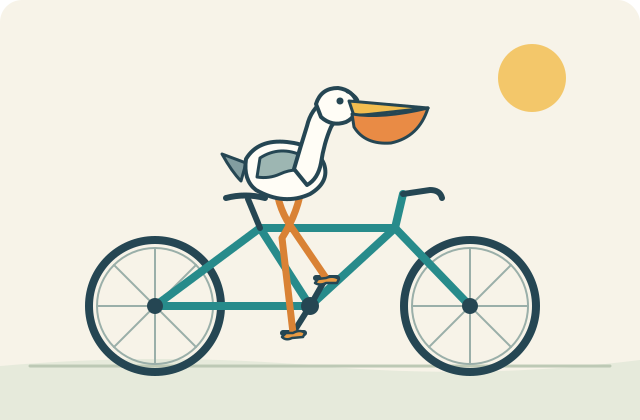
See this model’s pelican
See what GPT-6.1 Terra created from the same prompt.
Highlights
- Balanced mid-tier model in the GPT-6.1 series
- Combines visual reasoning with accurate computer operation
- 16.1 seconds per task, reported fastest OpenAI model
- Error rate 16.7% at low reasoning effort, down from 53.6%
- Handles scoped code fixes and agentic codebase investigation
Providers
Best priceCompare API prices across providers. Select a provider to view all charges and conditions.
| Uptime | ||||
|---|---|---|---|---|
| $1 | $5 | $0.05 | ||
| $0.5 | $2.5 | $0.025 | ||
| $2 | $10 | $0.1 |
Historical observations are not a live health check. Missing data does not mean an outage.
What $10 buys
- Input
- 10M tokens
- Output
- 2M tokens
Estimated from current input and output prices, before discounts.
Benchmarks
- 16.7%
Error rate on error-inducing prompts (low reasoning effort)
Down from 53.6% for GPT-5.6 Terra
- 4.3%
Error rate on error-inducing prompts (max effort)
An 18-point improvement, roughly on par with GPT-6 Astra and GPT-6.1 Sol
- 78.2%
Unnamed benchmark score
OpenAI internal benchmark
Scores as published by the model provider.
Reasoning
- Default effort
- medium
- Enabled by default
- Yes
- Always enabled
- No
- Available effort levels
- max / xhigh / high / medium / low / none
Quick Start
Drop-in code to call this model with Felo API Platform compatible APIs. Start in the Playground when you want to test prompts before writing code.
Get your API key
Create a key from your Felo API Platform account and set it as an environment variable.
export FELO_API_KEY="YOUR_API_KEY"Make your first request
Use this model ID with the Felo API Platform endpoint. Optional request headers such as X-Request-Id can help troubleshooting.
gpt-6.1-terraThis model is reasoning-capable. If your selected protocol and model route expose reasoning controls, preserve the returned reasoning metadata when continuing a conversation.
const response = await fetch("https://openapi.felo.ai/api/v1/responses", {
  method: 'POST',
  headers: {
    Authorization: `Bearer ${process.env.FELO_API_KEY}`,
    'Content-Type': 'application/json',
  },
  body: JSON.stringify({
  "model": "gpt-6.1-terra",
  "input": "Hello"
}),
});
if (!response.ok) throw new Error(await response.text());
console.log(await response.json());
Using third-party SDKs
Use compatible SDKs by setting baseURL to https://openapi.felo.ai/api/v1. Use the Anthropic-compatible base URL for Claude-style clients. https://openapi.felo.ai/api.
Enable streaming
Add stream: true to receive responses as server-sent events.
curl -N https://openapi.felo.ai/api/v1/responses \
  -H "Authorization: Bearer $FELO_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "gpt-6.1-terra",
  "input": "Hello",
  "stream": true
}'
Endpoint
Felo API Platform exposes compatible model-calling surfaces. Pick the surface your app or agent client already supports.
Responses
Responses-compatible agent and workflow requests.
POST
https://openapi.felo.ai/api/v1/responsesParameters
modelstringgpt-6.1-terraPublic model ID to call.inputstring | array——seed———toolsarray—Tool calling definitions following compatible schema.reasoning———verbosity———max_tokensinteger—Maximum generated tokens.tool_choicestring or object—Controls whether a tool should be called.response_formatobject—Request structured output when supported.reasoning_effort———include_reasoning———structured_outputs———max_completion_tokens———Frequently asked questions
What is GPT-6.1 Terra?
GPT-6.1 Terra is a mid-tier model in OpenAI's three-tier GPT-6.1 series, positioned between the flagship GPT-6.1 Sol and the fast, low-cost GPT-6.1 Luna. It combines detailed visual reasoning with accurate computer operation and writes clearer, more natural prose. Announced and made available on October 26, 2026, through ChatGPT Work, Codex, and the API, it is designed as a fast and efficient option for everyday professional work. The model supports text and image input with text output. It handles scoped code fixes, supports computer-use tasks with clearly defined outcomes, and is suited to agentic codebase investigation and iterative solution development. Everyday applications include drafting proposals, interpreting technical drawings, filling in forms, video editing, matching product photos with catalogs, and understanding complex documents. At 16.1 seconds per task, it is reported as the fastest OpenAI model and the third fastest overall. Its error rate on error-inducing prompts at low reasoning effort is 16.7%, down from 53.6% for GPT-5.6 Terra. At max effort, the error rate is 4.3%. In the lineup, it sits below the flagship GPT-6.1 Sol and the top-tier GPT-6 Astra.
How is usage billed?
Your bill depends on the provider you use, its prices and your usage. Longer inputs or other conditions may have different prices.
What input modalities does GPT-6.1 Terra support?
It accepts text and image input and produces text output.
What tasks is GPT-6.1 Terra suited for?
It is designed for everyday professional work such as drafting proposals, interpreting technical drawings, filling in forms, video editing, matching product photos with catalogs, and understanding complex documents. It also handles scoped code fixes, agentic codebase investigation, and iterative solution development.
How does GPT-6.1 Terra compare with other models in the GPT-6.1 series?
The GPT-6.1 series forms a three-tier structure of Sol, Terra, and Luna. GPT-6.1 Sol is the flagship tier, GPT-6.1 Terra is the balanced tier, and GPT-6.1 Luna is the fast, low-cost tier. GPT-6.1 Terra is positioned below the flagship GPT-6.1 Sol and the top-tier GPT-6 Astra.
How fast is GPT-6.1 Terra?
It completes tasks at 16.1 seconds per task, reported as the fastest OpenAI model and the third fastest overall. It also completes tasks more than 3 times faster than GPT-6 Astra.
How does GPT-6.1 Terra perform on error-inducing prompts?
At low reasoning effort, its error rate is 16.7%, down from 53.6% for GPT-5.6 Terra. At max effort, the error rate is 4.3%, an 18-point improvement roughly on par with GPT-6 Astra and GPT-6.1 Sol.
Related models
GPT-6.2 Astra Pro
OpenAIgpt-6.2-astra-proGPT-6.2 Astra Pro is OpenAI’s flagship frontier model for complex reasoning, coding, professional work, and scientific applications.
Context
1.05M
Max output
128K
Input tokens · Base rate
$8 / 1M tokens
Output tokens · Base rate
$40 / 1M tokens
GPT-6.2 Astra
OpenAIgpt-6.2-astraOpenAI GPT-6.2 Astra is a frontier model for complex professional work, multilingual vision tasks, coding, research, and bounded agentic workflows.
Context
1.05M
Max output
128K
Input tokens · Base rate
$8 / 1M tokens
Output tokens · Base rate
$40 / 1M tokens
GPT-6.2 Sol Pro
OpenAIgpt-6.2-sol-proGPT-6.2 Sol Pro is an efficient, versatile model for coding, writing, multi-step work, and interactive browser experiences.
Context
1.05M
Max output
128K
Input tokens · Base rate
$2 / 1M tokens
Output tokens · Base rate
$10 / 1M tokens
GPT-6.2 Sol
OpenAIgpt-6.2-solGPT-6.2 Sol is an efficient multilingual and vision-capable model for coding, automation, reports, and multi-step agent work.
Context
1.05M
Max output
128K
Input tokens · Base rate
$2 / 1M tokens
Output tokens · Base rate
$10 / 1M tokens
GPT-6.1 Terra Pro
OpenAIgpt-6.1-terra-proGPT-6.1 Terra Pro is OpenAI's mid-tier reasoning model that runs GPT-6.1 Terra with reasoning.mode set to pro for higher accuracy on hard, high-stakes tasks.
Context
1.05M
Max output
128K
Input tokens · Base rate
$1 / 1M tokens
Output tokens · Base rate
$5 / 1M tokens
GPT-6.1 Sol
OpenAIgpt-6.1-solGPT-6.1 Sol is OpenAI's near-flagship model for agentic coding, computer use, and document-heavy professional work, with a 1,050,000 token context and tiered reasoning controls.
Context
1.05M
Max output
128K
Input tokens · Base rate
$2 / 1M tokens
Output tokens · Base rate
$10 / 1M tokens