
In low-cost, high-context, systematic tasks, I'm finding GPT-5.6 Luna to still be better than GPT-6 Luna and better than Haiku 5.5.
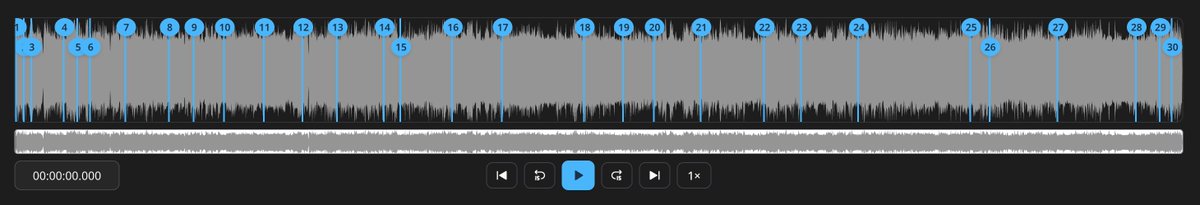
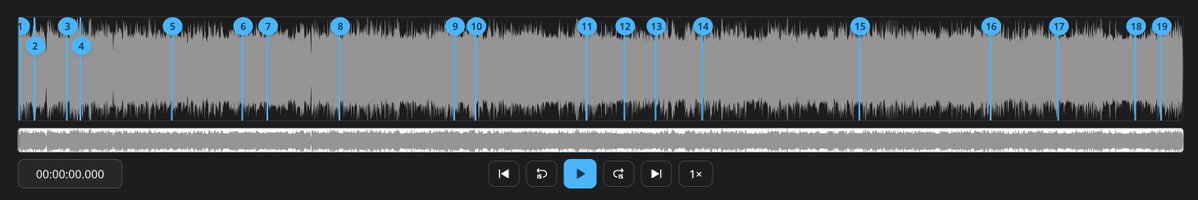
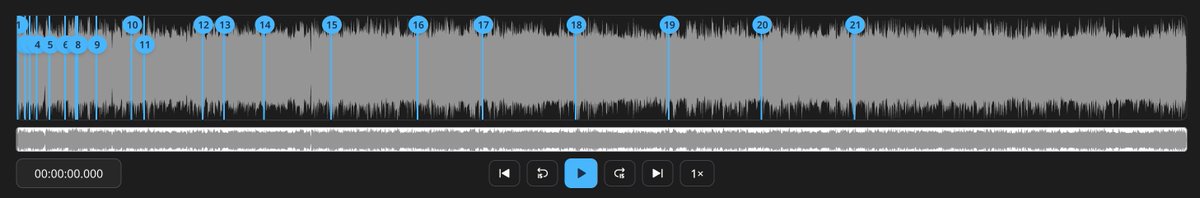
In low-cost, high-context, systematic tasks, I'm finding GPT-5.6 Luna to still be better than GPT-6 Luna and better than Haiku 5.5. Here's are some examples. My @PodChapters app helps podcasters create chapters that drive engagement in seconds. With a podcast episode about 2 hours and 10 minutes long, GPT-5.6 Luna offers a good spread of suggested chapters and respects my instructions for fewer, balanced, or more chapters (photo 1). With the exact same episode and instructions, GPT-6 Luna produced fewer chapters (photo 2). Claude Haiku 5.5 was the most disappointing and produced results I've seen from several frontier models when given large contexts. In this example (photo 3), Haiku produced too many chapters in the beginning of the episode, and none near the end. And this was only about 278K tokens. But Haiku was much faster than the GPT model, completing the tasks in an average of 4.1 seconds, while GPT-6 Luna was an average of 34 seconds, and 5.6 Luna was around 10 seconds.