
CASE / sean-youngenMon Sep 28
MEDIA / 1image
SSean Young@SeanYoung1995
圖像生成JEV
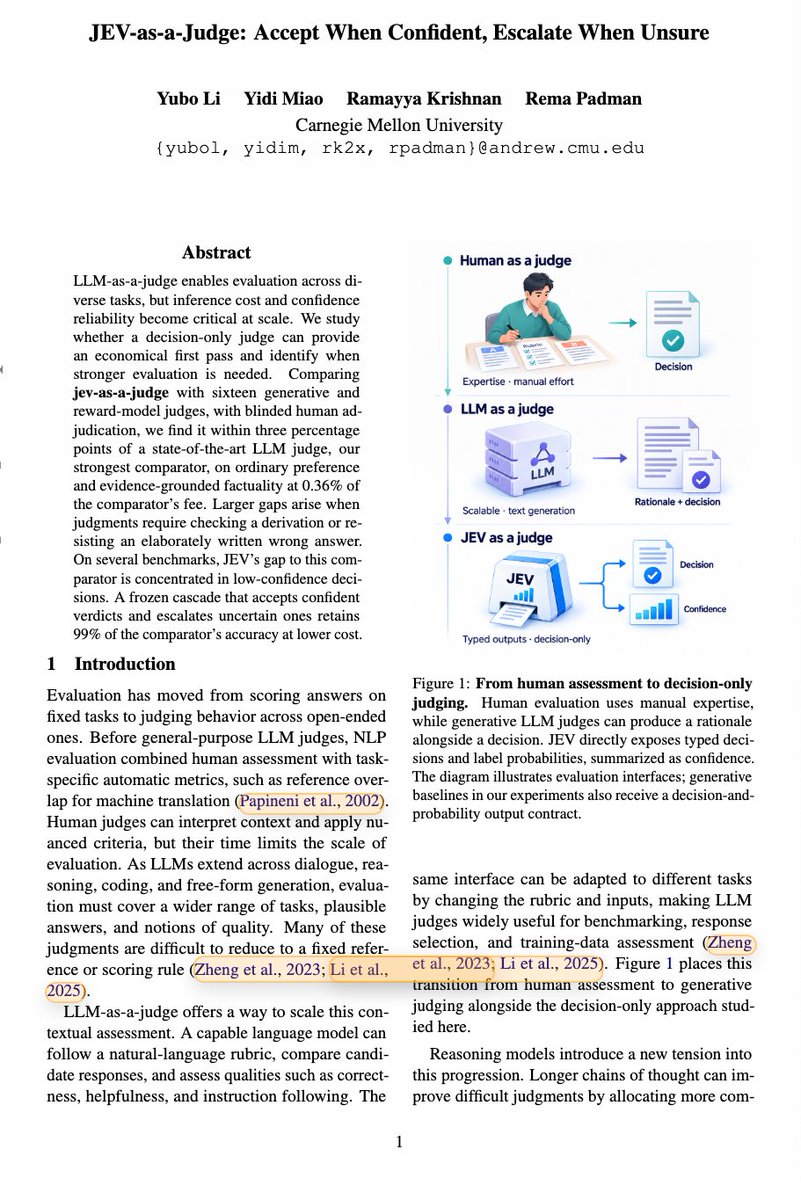
A cheap LLM judge nearly matches GPT-6, but struggles badly on harder tasks. Yubo Li, Yidi Miao, and Ramayya K
A cheap LLM judge nearly matches GPT-6, but struggles badly on harder tasks. Yubo Li, Yidi Miao, and Ramayya Krishnan at Carnegie Mellon University evaluated TypeSafe JEV 1.13 across preference and evidence factuality tasks, plus harder reasoning and adversarial settings.
Imagine a reviewer checking thousands of answers where most cases are straightforward, but some require deep reasoning. JEV acts as the cheap first reviewer, accepting confident decisions while escalating uncertain ones to a stronger model. This works when its confidence is trustworthy, but becomes risky when polished wrong answers or multi-step reasoning can fool the judge.
On ordinary preference and evidence factuality tasks, JEV stayed within three percentage points of GPT-6 while costing about 0.36% as much. On multi-step reasoning and adversarial-style tasks, the accuracy gap widened to more than ten percentage points.
https://t.co/h5yyauVF1y
52瀏覽
1讚
1收藏
0轉發